In short
Most product design processes are sold as a package: research, flows, wireframes, prototypes, UI, a design system, build, analytics, all of it, every time. The money leaks in the stages your product never needed. We start by finding what actually failed, pick only the stages that reduce that risk, make the user flow the document everyone trusts, test cheap versions before paying for code and decide how success will be measured before release.
In this article
- What the product design process actually is
- Why the textbook diagram lies to you
- Start at the crime scene: find out what actually failed
- Choose the stages by risk, not by package
- A new product has no crime scene yet
- Research that answers a question, not a curiosity
- The user flow is the source of truth
- Validate cheap representations before expensive implementation
- UI design comes late, and it has to cover every state
- A design system is a tool, not a trophy
- Documents earn their keep only when they support a decision
- Implementation: where the design meets the bill
- Who owns what in the process
- Decide how you will know it worked, before you release it
- The mistakes that make the process expensive
- When a full redesign is the right call
- How long does the product design process take?
- How ANODA runs the product design process
- The decision rule
A product design process is not a conveyor belt every product rides from research to launch. It is a set of tools you pick up in the order your problem demands: find out what actually failed, choose only the stages that reduce that risk, make the user flow the one document everybody trusts, test cheap versions before you pay for code, and decide how you will know it worked before anyone ships. Everything else is a brochure.
Our experience fixing complex products keeps showing us the same problem, and the brochures have barely changed. Eight tidy stages, a friendly arrow, a promise that research leads to insight and insight leads to delight. Then the product launches, trial users sign up, and most of them never do the one thing the product exists for. The company paid to acquire every one of them: ads, sales calls, content, partner fees. The money came in through the front door and walked straight out the back.
So when a founder asks us for “the full product design process”, our first question is a rude one. What died?
We treat every project as a crime scene. Before anybody sells you a redesign, someone has to establish what actually failed, where, and why. Sometimes the answer needs research, flows, wireframes, prototypes, a new interface, a design system, implementation and analytics. Often it needs three of those. Occasionally it needs one afternoon and a changed default. The stages are real. Buying all of them by default is how design budgets disappear without a trace.
AI has not changed the plot. Tools now produce screens in seconds, which means a team can produce the wrong screens in seconds too. Speed was never the bottleneck. Knowing what to build was.
What the product design process actually is
The product design process is the chain of decisions a team makes to turn a business problem into a product change people actually use. What is wrong, and for whom. What should happen instead. How that works, step by step. What it looks like. How it gets built. How you will tell whether it helped.
The deliverables are just how those decisions get written down. Research notes, user flows, wireframes, prototypes, interface designs, a design system, working code, a measurement plan. Each one exists to settle a question. When it settles nothing, it is decoration you paid for by the hour.
Here are the stages you will meet in almost every guide, including this one, with the column the guides usually leave out.
| Stage | The question it settles | It is waste when… |
|---|---|---|
| Diagnosis | What actually failed, where, and what it costs | Never. This is the one stage we do not skip |
| Research | What users need, do and misunderstand in this specific situation | The evidence already answers the question, or no decision depends on the answer |
| User flows | Which steps, states, decisions and failure paths the product must support | The change is purely visual and no step moves |
| Wireframes | Where things go and in what order, before anyone argues about colour | The layout is already proven and the change is copy or data |
| Prototypes | Whether real people can complete the task before code exists | The change is small, reversible and cheap to ship and measure |
| UI design | How each state looks, reads and behaves on real screens | Nobody has agreed on the flow yet |
| Design system | How the interface gets built consistently and fast by several people | One team, one product area, and the product is still looking for its market |
| Implementation | Whether what ships matches what was decided | Never skipped, only neglected |
| Analytics and monitoring | Whether the change did what it was meant to do | Nobody will act on the result, which is its own diagnosis |
Read the last column slowly. Nearly every stage has a condition under which it is money set on fire. The brochure never prints that column, because the brochure is priced per stage.
You will also hear the process described through a methodology: design thinking, lean, agile, jobs to be done. They are useful lenses, and none of them is the process. Design thinking tells you to understand before you solve. Lean tells you to test the riskiest assumption cheaply. Agile tells you to ship in small increments. Jobs to be done tells you to describe the progress a customer is trying to make. Pick up whichever lens helps with the question in front of you. Just do not confuse owning the vocabulary with having done the work.
Product design is also wider than the UX process, and the difference matters when you are buying it. UX work owns research, structure and usability. Product design takes those and drags them into the commercial world: the business model, the build, the release, the numbers afterwards. If you want the narrower view, our guide to the UX design process from research to testing covers it. This article is about the whole route from “something is losing money” to “we know whether the fix worked”.
Why the textbook diagram lies to you
Every product design process diagram is a straight line. Discover, define, design, build, launch. It looks rigorous. It is a motorway drawn across a city that is mostly roundabouts.
Real projects loop. A prototype test exposes a research gap. A flow review reveals a permission rule nobody wrote down. Engineering finds that the data the design relies on does not exist in the shape the designer assumed. None of this is failure. It is the process working. The failure is the diagram that pretends it will not happen, and the contract written against the diagram.
Even the people who drew the most famous diagram say so. The UK Design Council, which started work on its Double Diamond (discover, define, develop, deliver) in 2003, later expanded it into its Framework for Innovation, and its own history page, as of 2026, says why: organisations keep discovering underlying problems that send them back to earlier stages, digital products are rarely truly finished, and early prototyping can be part of discovery itself. The diamond’s authors grew out of the straight line. Plenty of agencies still sell it.
The second lie is subtler. Teams copy a process from a company they admire and apply it to a product in a completely different situation. It is copying a classmate’s maths homework, mistakes included, for a different set of problems. Their eight-week discovery made sense for a new product line with no users. Your product has thousands of paying accounts and one broken step. You do not need eight weeks of discovery. You need to look at the broken step.

Why do agencies love the straight line? Because it is easy to price. Eight stages, eight line items, one invoice schedule. Nobody has to explain why stage three was skipped, or admit that stage five turned out to be unnecessary. The client feels thorough. The agency feels safe. The product gets everything except the one thing it needed: attention on the actual problem.
A package protects the seller. ANODA starts with the diagnosis that protects your budget and points the work at the problem losing customers.
Audit check
Take your current or proposed design plan and write, next to every stage, the decision it will settle and what happens to the project if that stage is skipped.
Failure evidence
Stages justified by “best practice” or “that is how the process works”. Nobody can name the decision a stage feeds. The plan looks the same as the last three plans from the same vendor, for three different products.
Correction pattern
Keep the stages that settle a decision you actually face now. Park the rest with a named trigger for bringing them back.
Start at the crime scene: find out what actually failed
A detective does not arrive at a crime scene and start redecorating the living room. They secure the scene, collect evidence, list the suspects and check each alibi. Only then do they name a culprit. Product teams do the opposite. They arrive, look around, decide the place looks dated, and order new furniture.
Here is how that usually plays out. We will use an illustrative example rather than a client story, because the pattern is more useful than the name.
Crewline (a fictional product) is a scheduling tool for small field-service companies: plumbing, heating, electrical. An office manager signs up for a trial, adds the technicians, creates jobs and assigns them, and the technicians get the jobs on their phones. The company spends real money on ads and on a sales team that runs demos. Trial sign-ups arrive. Paying customers do not follow.
The team’s theory arrives before any evidence does. “The UI looks dated. Competitors look slicker. We need a redesign.” There is already a mood board. There is already a quote for a new design system. Somebody has already said “rebrand” in a meeting.
Now let us do what a detective would do.
Secure the scene. Write down the exact symptom in business terms, before anyone proposes a fix. Not “users don’t like the app”. Something like: trial accounts are created, but few of them schedule a first job, and accounts that never schedule a first job almost never convert. That sentence already tells you where to look. The money is lost between sign-up and the first scheduled job.
Collect the evidence. Everything the product already knows, before a single new interview:
- the funnel from sign-up to first job, step by step, from product analytics;
- session recordings of new trial accounts, especially the ones that stall;
- support tickets and chat logs from trial users;
- notes from sales demos and lost deals;
- cancellation reasons, however lazy the form that collects them;
- and the product itself, walked end to end as a brand-new user, on a real phone, with no admin shortcuts.
Be careful with witnesses, too. Some of the evidence in any product is unreliable, and a good investigation knows which:
- Analytics are only as honest as their setup. An event that fires on page load instead of on completion will tell you a step is fine when nobody finishes it.
- Surveys collect what people are willing to type, not what they did. The polite answer and the true answer are rarely the same answer.
- The loudest customer is one data point with a large voice. Their request may be right. It is still one account.
- Internal opinion — sales, the board, the founder’s partner — is a theory, not evidence. Treat it like any other suspect: welcome, and checked.
Where two sources agree, you are getting close. Where the recordings and the funnel point at the same step, you have your prime suspect.
List the suspects and check their alibis. Each theory becomes a suspect, and each suspect has to survive the evidence.

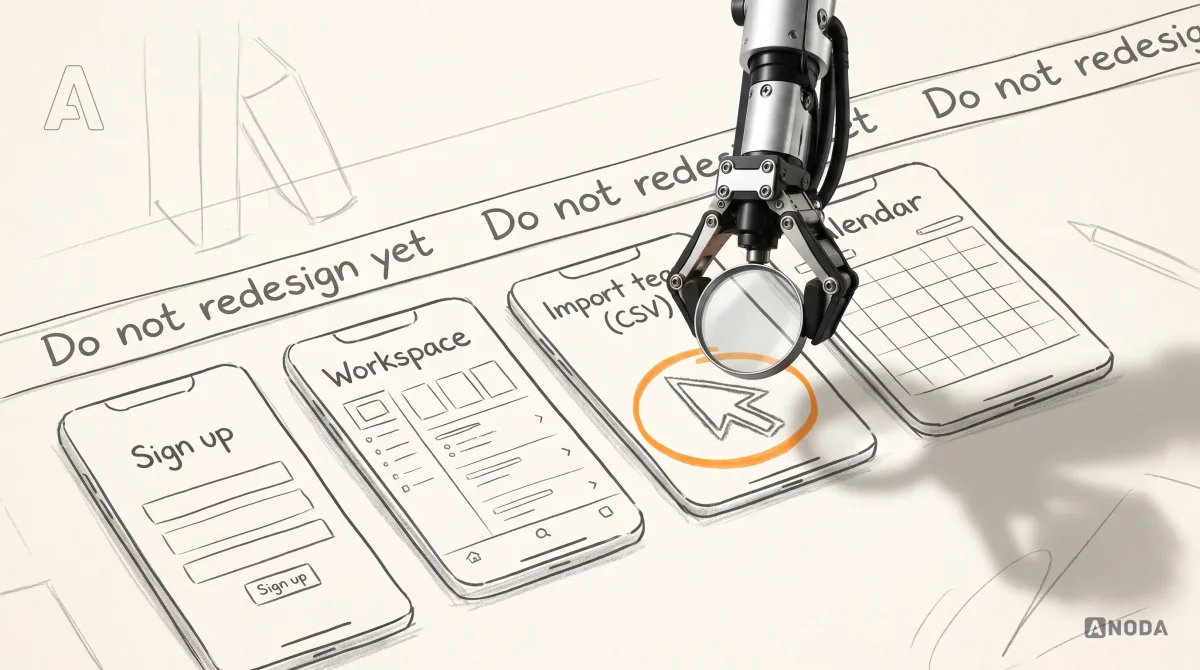
In the Crewline case the evidence tells a different story from the meeting. The recordings show new office managers hitting a step that asks them to upload every technician as a CSV file before they can see the calendar. They do not have that file. They leave to make it, and they do not come back. That is the smoking gun. The “dated UI” is a red herring: nobody in the lost-deal notes mentions the look, and the demos, where a salesperson drives, go fine. The problem is not what the product looks like. It is what the product demands before it gives anything back.
Before anyone deletes that step, remember Chesterton’s fence: if you find a fence in the middle of a field, do not tear it down until you know why someone put it there. Somebody built the import first for a reason. Maybe a large early customer insisted on bulk setup. Maybe the scheduling engine could not run without a list of technicians. The fix is not always removal. Often it is order: let the manager create one job and assign it to themselves first, and offer the import once they have seen the product do something useful.
Look at what the diagnosis just saved. The redesign would have taken a quarter, maybe two. The new interface would have looked gorgeous and kept the CSV step, because nobody had identified it as the problem. It would have papered over the cracks with better typography while the same trial users walked out at the same step, now in a nicer font. Meanwhile, every month the team spends not finding the cause, it chooses to keep paying for trial users who leave at step two.
A redesign without a diagnosis is a very expensive way to keep the same problem.
Audit check
Before approving any design work, write the symptom as a business sentence, list the evidence you already have, and name every theory as a suspect with the evidence for and against it.
Failure evidence
The solution is named before the problem (“we need a redesign”, “we need a design system”). Nobody has walked the product as a new user this quarter. The team cannot say at which step the money is lost.
Correction pattern
Run the diagnosis first, even if it takes a week. Let the evidence pick the culprit, then let the culprit pick the stages.
Choose the stages by risk, not by package
Once you know what failed, the process picks itself. You choose the stages that reduce the specific risk in front of you, and you leave the rest on the shelf until a real risk calls for them.
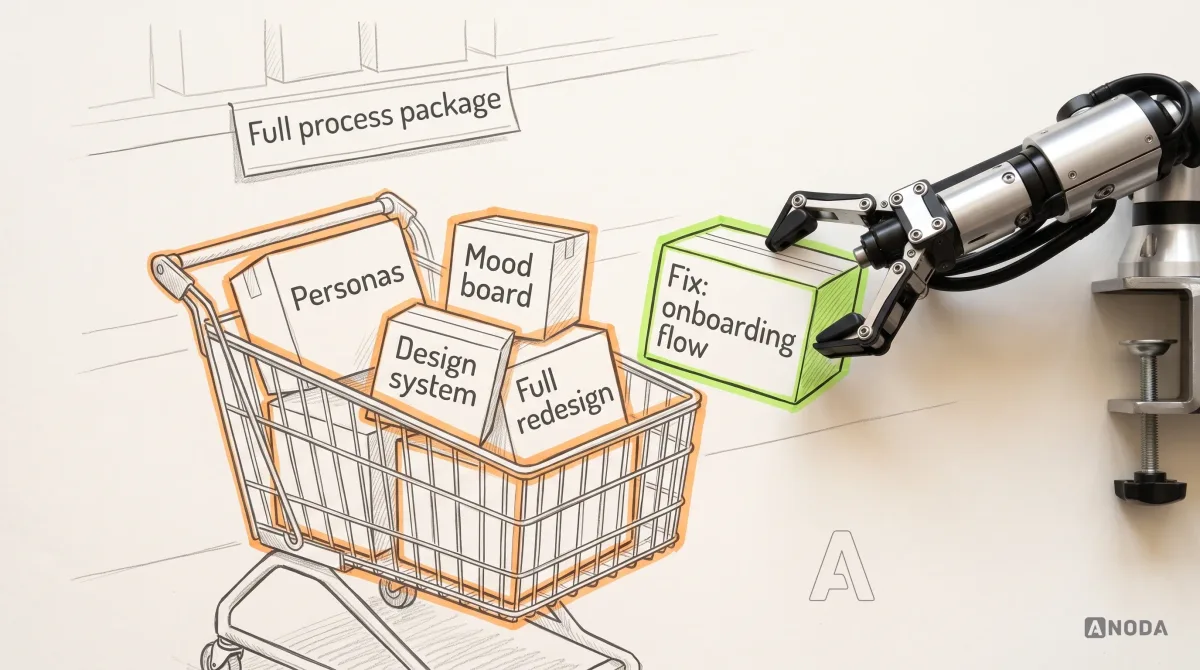
Most design proposals work like a supermarket multipack. You needed one lemon. The only option on the shelf is a bag of twelve, and eleven go mouldy at the back of the fridge. The full-process package is sold the same way: research, personas, journey maps, flows, wireframes, prototypes, UI, a design system, all bundled, because the bundle is easier to quote than your actual problem. You pay for twelve lemons and you get lemonade you did not order.
It is horses for courses. A product that nobody understands needs research. A product people want but get lost in needs flows and prototype testing. A product that works but is slow and inconsistent to build needs a design system. A product that looks fine in the design file and wrong in production needs someone watching the build. Buying the same package for all four is buying a pig in a poke: you only find out what was in the bag after the money is gone.
Here is the map we use to match the risk to the stages.
| The risk you have now | Stages that reduce it | Stages that can wait |
|---|---|---|
| Nobody knows why users leave | Diagnosis, then targeted research | UI refresh, design system |
| Users want it but get lost on the way | User flows, wireframes, prototype tests | Brand refresh, design system |
| The flow works, the interface is inconsistent and slow to build | UI design, design system | A new research round |
| The design is right, the built product is not | Implementation support, design QA | New concepts |
| It shipped and nobody knows if it helped | Analytics, monitoring, follow-up research | Another redesign |
| New product, no users yet | Research, flows, prototypes | A full design system |
Notice that “redesign” is not a risk. It is a solution that someone has named too early. When it appears in the left-hand column of a brief, we move it to the right and ask what it was supposed to fix.
The same map also works backwards, as a smell test for proposals you have already received. If a vendor quotes you a design system for a product that has not found its market, or a research programme for a problem the evidence has already solved, they are selling the stage they are best at, not the one you need.
This is also the moment to decide where the work stops. Some teams need an outside partner for the whole route. Others need the diagnosis and the validated flow, and have engineers who will happily take it from there. Both are legitimate. The expensive option is the one nobody chose deliberately.
How we work
Not sure which stages your product actually needs?
Bring us the symptom and whatever evidence you have. We will tell you which stages reduce the risk, which ones can wait, and where our part should stop.
A new product has no crime scene yet
Everything above assumes a live product with evidence to collect. A new product has no users, no funnel and no recordings. There is no body on the floor. That does not mean you skip diagnosis. It means you diagnose the plan instead of the product.
For a new product the risk is building something nobody needs badly enough to pay for. The suspects are the assumptions: that this group of people has this problem, often enough and painfully enough, and that they will change how they work to solve it. Every assumption stays a suspect until someone has evidence for it.
So the stages shift towards the front. Research carries more weight, because there is no usage data to lean on: conversations with the people you intend to sell to, and a close look at how they solve the problem today. The spreadsheet, the group chat, the whiteboard by the office door. What that workaround costs them in time and mistakes is the size of your opportunity. Then come flows and prototypes for the smallest version of the product that can prove the core job works.
That smallest version is where most new products overspend. The MVP turns into everything the founder imagined, minus whatever engineering flatly refused. A useful MVP is defined by the one job it must do end to end, not by its feature list. For a scheduling tool, that job might be: a manager gets a job onto a technician’s phone and knows it was accepted. Invoicing, route planning, customer portals and reports are all real features. None of them proves the core job. They can wait for evidence.
What a new product can safely postpone: a full design system, because the interface will change too much to standardise; heavy polish on flows that are still moving; and elaborate dashboards before there are enough users to read them. What it cannot postpone: a clear flow for the core job, a prototype tested with real target users, and a decision about which signal will tell you the product is working.
Money in a new product is runway. Every month spent building features nobody validated is a month less to find the ones that matter. A product that spends its runway on polish has chosen to look finished instead of being useful.
Research that answers a question, not a curiosity
Research is the stage most often sold by the kilo. Twenty interviews, three personas, a journey map for every segment. It sounds diligent. Then someone asks what decision the research changed, and the room goes quiet.
Good research starts from a decision you cannot make yet. “Should the first thing a new office manager does be scheduling a job or importing a team?” is a research question. “Understand our users” is not. It is a hobby.
Back at the crime scene, a detective with a fingerprint on the doorknob does not canvass the whole neighbourhood about the weather. They follow the lead. Research works the same way. Once the diagnosis has a prime suspect, research confirms or clears it, and fills the gaps the data cannot see: why the step is a problem, what the user expected to happen, what they did instead.
For Crewline, that means a handful of conversations with office managers at small field-service companies, and a few task-based sessions where they try to schedule a first job in the current product while someone watches and keeps quiet. Nobody needs a persona deck for that. They need to hear, in the manager’s own words, that they did not have a list of technicians in a spreadsheet, and that they signed up to see whether the calendar would work for Monday.
Match the method to the question, not to habit:
- Why do people do this? Interviews and observation, with people in the target segment.
- Can they do it? Task-based usability sessions on the real product or a prototype.
- How many of them, and where do they stop? Product analytics, if the events can be trusted.
- What do they complain about? Support tickets, chat logs and cancellation reasons, read in bulk.
You also do not need hundreds of participants to find a broken step. Jakob Nielsen argued back in March 2000, in “Why You Only Need to Test with 5 Users” on the Nielsen Norman Group site, that a budget is better spent on three small studies of five users each than on one big one: test, fix, test again. The principle has aged well. Small, repeated rounds catch more of what matters than one grand study that arrives after the decision was already made.
Where does AI fit? It is genuinely useful for the boring parts: transcribing, tagging support tickets, clustering thousands of cancellation reasons into themes a human can read in an hour. It is useless as a replacement for the people themselves. AI can summarise the interviews you ran. It cannot interview the customers you never called, and synthetic users built from a prompt tell you what the prompt already believed.
The money line is simple. Research that feeds no decision is a bill with footnotes. Research aimed at the prime suspect is the cheapest insurance you will ever buy against building the wrong fix.
Audit check
For every research activity in the plan, write the decision it will inform and the answer that would change your mind.
Failure evidence
Research outputs that are admired and filed. Personas nobody quotes in a design review. Findings that arrive after the build started.
Correction pattern
Tie each round to one open decision, keep rounds small and repeated, and bring findings into the flow and the backlog the same week.
The user flow is the source of truth
If we had to keep only one document from the entire product design process, it would be the user flow. Not the mood board, not the persona deck, not even the polished screens. The flow.
Think of the seating plan at a big family wedding. The caterer counts plates from it, the florist places centrepieces by it, the photographer knows where the grandparents are, and the best man knows which uncle must never be seated near which ex-wife. Nobody argues about the plan at the reception, because everybody agreed it before. Now imagine each supplier working from their own version. The food arrives at empty tables, Grandma sits by the speakers, and the uncle finds his ex-wife on table four. That is a product team where design, engineering, QA, support and analytics each work from their own idea of how the product behaves.
A user flow worth trusting contains more than happy-path arrows:
- the trigger that starts the journey and the state the user arrives in;
- every step and the decision the user makes at it;
- the states of each screen: empty, loading, partial, error, no permission, done;
- the failure branches and where each one leads next;
- the roles involved, when more than one person touches the job;
- and the outcome that counts as success, in terms the business cares about.

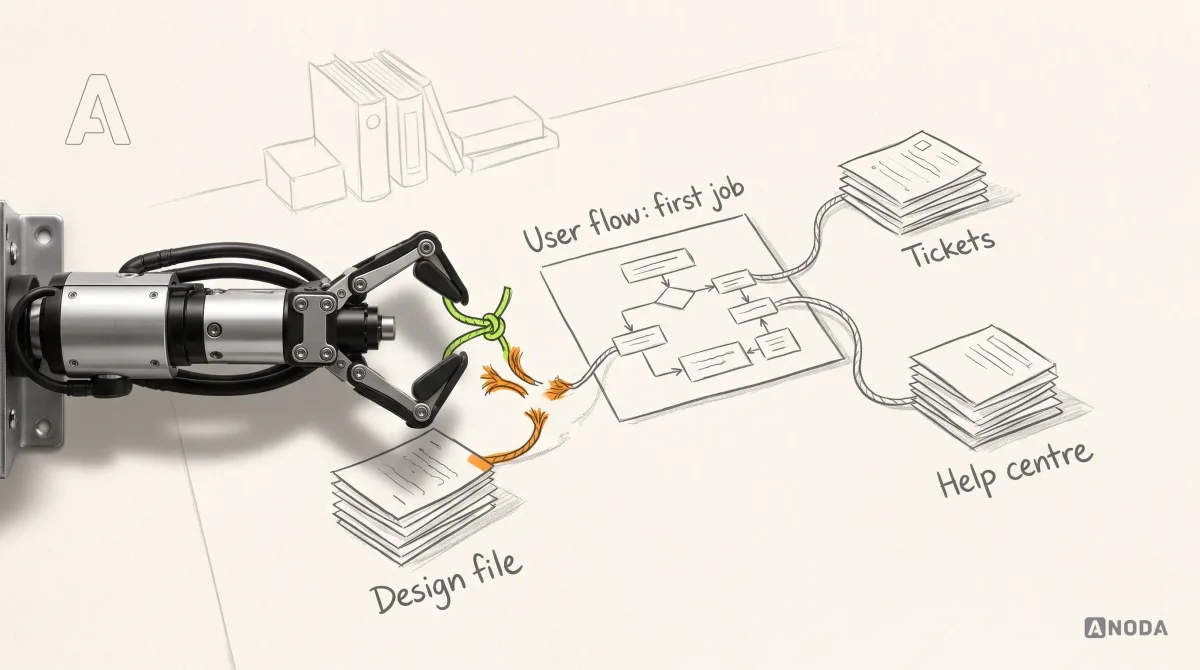
In the Crewline flow above, the fix lives in the structure, not the styling. The calendar comes first, with an empty state that asks for one job. The team import becomes a side branch the manager can take now, later or never. A manager with no technicians invited yet can assign the job to themselves and see the whole loop work. Every step in that flow has a name, and those names become the analytics events, the acceptance criteria, the QA scripts and the help-centre article titles. One vocabulary, from the design file to the dashboard.
That is what “source of truth” means in practice. When a question comes up — what happens if a technician declines, what does a manager see if the import fails halfway — the answer is in the flow, or the flow gets updated before the answer goes anywhere else. When the product changes, the flow changes first. A flow that is not maintained becomes last year’s seating plan, and people stop trusting it for exactly the right reasons.
Why is this the document worth money? Because every mismatch between what design intended, what engineering built and what support explains is a bug that a paying customer finds first. The flow is where you catch those mismatches for the price of a meeting instead of the price of a churned account.
Audit check
Pick your most valuable journey and ask design, engineering, support and analytics to each describe its steps and failure states separately. Compare the answers.
Failure evidence
Four different descriptions. Analytics events named differently from the screens. Failure states that exist in code but in nobody’s diagram.
Correction pattern
Agree one flow per critical journey, name its steps once and reuse the names everywhere, and update the flow before any change to the journey ships.
Validate cheap representations before expensive implementation
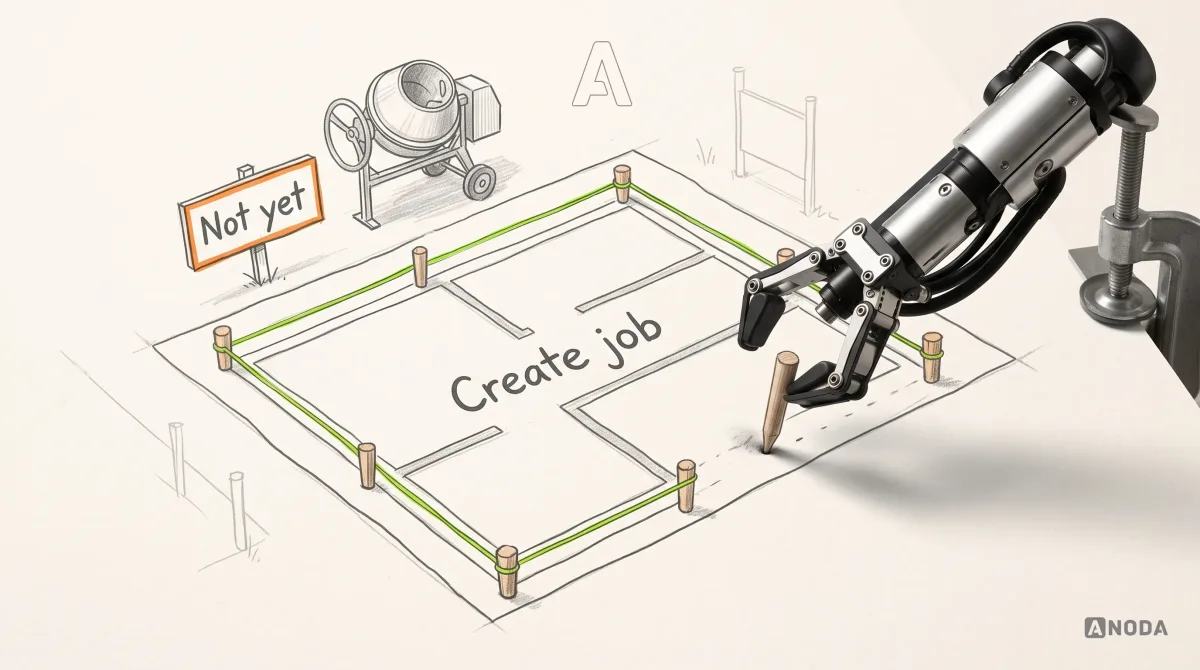
Builders mark out a house with wooden pegs and string before the digger arrives. Walk around the string, and you notice the kitchen window faces the neighbour’s bins. Moving a peg takes a minute. Moving a wall after the concrete has set takes a month and a very awkward conversation with the bank.
Product teams skip the pegs all the time. The flow goes straight from a whiteboard photo into sprint planning, and the first time a real user touches it is in production. Then every correction costs engineering time, QA time, release coordination, and the patience of the customers who met the broken version first.
The rule is simple: use the cheapest representation that can answer the question you have right now.
- A sketch or a flow diagram answers “is this the right sequence?” in minutes.
- A wireframe answers “does the order and the priority on this screen make sense?” without anyone arguing about colours.
- A clickable prototype answers “can a real person complete the task?” before a line of production code exists.
- A coded prototype answers questions only real data or real performance can: does the schedule view hold up with forty technicians, does the address search feel fast enough on a site with no signal.
- Production code behind a flag answers “does it work at scale, with real customers?” — the most expensive way to ask anything, so save it for the last question, not the first.
A printer runs one proof copy before printing ten thousand brochures. A typo on the proof costs a pen stroke. The same typo on the print run costs the print run. A prototype test is the proof copy: small, fast, and much cheaper than finding out from a pallet of brochures nobody can use.
For Crewline, the new order — calendar first, one job, team later — would be tested as a clickable prototype with a few office managers before any engineer touches the onboarding code. Give them a real task (“You have a boiler repair on Monday at 9. Get it into the schedule.”), watch where they hesitate, fix, test again. Three rounds of that cost a fraction of one sprint.
And when the prototype confirms the direction, the screens themselves become an easy, specific piece of work instead of a debate.

There is one trap with cheap representations, and AI has made it bigger. Prototypes now look finished. An AI tool can turn a prompt into a polished, clickable app in an afternoon, and stakeholders treat anything that polished as approved. Keep the purpose of the representation in the room: it is there to answer one question, and when it has answered it, it goes in the bin. Nobody moves into the pegs and string.
Audit check
For the next significant change on your roadmap, name the riskiest assumption and the cheapest representation that could test it.
Failure evidence
The first real user test happens after launch. Prototypes are used for sign-off, not for testing. Feedback rounds argue about colour while the sequence is still unproven.
Correction pattern
Test sequence with flows, layout with wireframes, task completion with prototypes, and only then commit engineering time. Repeat small rounds instead of one big one.
UI design comes late, and it has to cover every state
Visual design is the stage every client wants to start with, because it is the stage you can see. It belongs near the end of the sequence, not because it matters less, but because it is the most expensive thing to redo. Polish a screen before the flow is settled and you will polish it twice.
Done at the right moment, UI design is specific, unglamorous and full of decisions. Which information comes first on the schedule view when an office manager opens it at 7am. How a job that clashes with another one looks. What the technician’s phone shows when the address is missing. How the calendar reads on a small laptop in a van. What the button says: “Schedule job”, not “Submit”. What colour means, and what it never means, so a red dot is a problem and not somebody’s brand preference.
The bulk of the work is in the states nobody photographs for a portfolio:
- Empty. The first calendar a new account sees. It either invites the first job or looks broken.
- Loading and partial. A schedule that loads in pieces must not look like a schedule with no jobs.
- Error. An import that fails on three rows out of forty should say which three and let the manager fix them, not throw the whole file back.
- No permission. A technician who opens the manager’s view should learn why they cannot see it and what they can do instead.
- Done. The moment the first job is accepted deserves a clear confirmation, because it is the moment the product proved its worth.
Two more things belong to UI design, not to a later “compliance phase”. Accessibility: contrast that survives a sunny van windscreen, touch targets suited to real working conditions, labels a screen reader can announce, focus order that makes sense on a keyboard. And responsiveness: the office manager plans on a laptop, the technician lives on a phone, and each needs the version of the screen that suits their job, not the same layout squeezed.
This is also where AI screen generators are the most tempting and the least useful on their own. They are parrots: fluent, colourful, very confident, and with no idea what they are saying. Ask one for “a scheduling dashboard” and you get a handsome grid of cards that looks like every other scheduling dashboard, with no empty state, no clash handling and no idea which decision an office manager makes at 7am. It is confident crap about a user it has never met. Use these tools to explore layouts quickly, by all means. Just do not let a parrot write your spec.
The money in UI design is quiet but real. A screen that explains itself saves a support ticket every time someone opens it. A screen that confuses costs the ticket, the agent’s time and, often, a trial that never converts. Multiply either by the number of people you paid to bring to that screen.
Audit check
For each screen in your critical journey, list its states — empty, loading, partial, error, no permission, done — and check whether each one has a design and a line of copy.
Failure evidence
Designs that exist only for the happy path with perfect data. Engineers inventing error messages on the day. “Something went wrong” appearing in more than one place.
Correction pattern
Design the states from the flow before the hero screen gets polished, and review the build state by state, not screenshot by screenshot.
On a phone, diagnose the whole task before refreshing the screens
An app can look ready in Figma and lose the customer when the keyboard opens, the camera permission is declined or the connection drops during payment. Buying a new visual style leaves those failures in place. The process has to follow a real mobile task through its interruptions, then give engineering the platform behavior and recovery states to build.
Forever Beauty shows that route. ANODA audited the live AI and AR beauty app, rebuilt its information architecture and redesigned sign-up, scanning, plans and live-camera makeup steps while keeping the existing backend. The client received the mobile UI, audit and reusable kit; its team owned the app and its AI and AR implementation.
For that scope, mobile app design connects onboarding, touch and keyboard behavior, permissions and complete task states into one buildable phone experience. You keep the process focused on what stops people reaching value, instead of paying to repaint the same broken journey.
A design system is a tool, not a trophy
A professional kitchen runs on mise en place: every ingredient chopped, measured and in its place before service starts, so nobody stops mid-order to look for the shallots. It works because it is prepared for the menu the kitchen actually serves. Nobody preps forty garnishes for a menu with three dishes.
A design system is the same idea for an interface: shared components, tokens for colour, type and spacing, patterns for common problems, and documentation that tells designers and engineers how to use them. When several teams build the same product, it stops each of them reinventing the wheel, and it makes the fifth version of a date picker unnecessary. When it is built for a product that has one team and one flow and has not found its market yet, it is a white elephant: expensive to build, expensive to maintain, admired in the kick-off deck and ignored in the codebase.
Signals that a design system will pay for itself:
- more than one team ships interface into the same product;
- the same component exists in several slightly different versions in production;
- simple interface changes take engineers longer than they should because nothing is reusable;
- the product has settled on its core flows, so the components will not be redesigned next month.
Signals that it can wait:
- the product is still changing its core flow every few weeks;
- one small team designs and builds everything, and talks every day;
- nobody has agreed who will own and maintain the system once it exists.
What goes into a first version is less than most teams expect. Tokens for colour, type and spacing, so the basics stop drifting. The dozen or so components your critical journeys actually use, built in code with their states. A few patterns for recurring problems, such as forms, empty states and errors. And a page of documentation per component that answers the question an engineer asks at 5pm: when do I use this, and when do I not?
When it is time, build it from what the product already uses, not from a catalogue of everything a product could ever need. Start with the components that appear on your critical journeys, make sure they exist in the code and not only in the design file, and give the system an owner. A design system without an owner starts decaying the week it launches.
Audit check
Count how many versions of your most common components — buttons, inputs, date pickers, tables — exist in production, and check whether the design library and the code library match.
Failure evidence
A beautiful component library in the design file that engineering does not use. Components nobody has touched since the kick-off. No named owner.
Correction pattern
Build or trim the system around the components your critical journeys use, keep design and code in step, and assign an owner before adding anything new.
Documents earn their keep only when they support a decision
Every design process produces paper. Research reports, personas, journey maps, flow diagrams, wireframes, prototype files, specs, component libraries, analytics plans. Some of it is the most valuable thing the project leaves behind. Some of it is the product-design version of a pupil who spends the whole lesson colouring in the title page and never writes the essay. It looks like work. It was work. It helped nobody decide anything.
Our rule is blunt. A document is worth keeping only if it supports a decision someone still has to make, and only if someone will keep it true. Everything else gets archived, merged into something alive, or never produced in the first place. For a deeper list of what a project can hand over, and what each artefact is for, see our guide to UX design project deliverables.
The “keep it true” part matters as much as the decision. Electricians keep as-built drawings, because the wiring never ends up exactly where the original plan put it. The as-built drawing is the one the next electrician trusts. A design file that no longer matches production is an old plan of a house that has since had two extensions: worse than no plan, because someone will believe it.

For each document in your project, four questions do most of the sorting:
- Which decision does it support? Name it. “Reference” is not a decision.
- Who owns it? One person, not “the team”.
- When does it get updated? Tie it to an event: a flow change, a research round, a release.
- Who actually reads it? If the honest answer is nobody, you already know the verdict.
The money here leaks slowly. Hours spent producing documents nobody uses. Hours spent maintaining documents nobody trusts. And, worst, decisions made from documents that stopped being true a year ago. Nobody sends an invoice for that last one, but you pay it anyway.
Audit check
List every design document your team maintains and answer the four questions for each: decision, owner, update trigger, readers.
Failure evidence
Documents with no owner. Several versions of the same flow. A design file that shows screens production retired months ago.
Correction pattern
Keep the flow, the live design files and the measurement plan as the working set; merge or archive the rest; and make updating the flow part of the definition of done.
Implementation: where the design meets the bill
Handoff is where good design most often dies quietly. Most of the screw-ups we get called in to fix were never design mistakes. They were decisions lost somewhere between the design file and the build. The design file goes over the wall, engineering builds what it can interpret, and a few weeks later the product ships something that resembles the design the way a delivery that does not match its delivery note resembles the order. The lorry arrives, the paperwork says one thing, the boxes say another, and the warehouse signs for it anyway because the lorry is already late.
Implementation support is not a designer hovering over an engineer’s shoulder. It is a short list of habits:
- Acceptance criteria written from the flow. Every step and state in the flow becomes something QA can check, so “done” means the empty state, the error and the permission case exist, not just the screenshot.
- A designer in the sprint. Questions come up daily: data arrives in a different shape, a component behaves oddly, a performance limit forces a trade-off. Each one answered in an hour costs nothing. Each one guessed costs a rework ticket.
- Design QA on the real build. Walk the flow in staging on real devices, state by state, before release. Not a pixel hunt. A check that the product does what was decided.
- Trade-offs made out loud. When engineering needs to cut scope, the flow shows what the cut breaks, and product decides with that in view.
For Crewline, the change is small in code and large in consequence: reorder onboarding, add the calendar’s empty state, allow self-assignment, move the import to a side branch, and make sure the failure path for an uninvited technician exists before release. Small enough to ship in a normal sprint. Important enough to deserve a designer checking it.
Release matters too. A change to a journey that carries revenue should reach a slice of new accounts first, behind a switch the team can turn off, with the measurement plan already running. If the numbers or the support queue go the wrong way, you roll back a switch, not a quarter.
Every “we’ll fix it after launch” gets fixed eventually. The question is whose patience pays for it in the meantime. Usually it is the customers you spent the most to acquire.
Audit check
Compare the last release of a critical journey with its flow and designs, state by state, on a real device.
Failure evidence
States that were designed but never built. Error messages written by whoever was on call. Designers who first saw the build after release.
Correction pattern
Write acceptance criteria from the flow, keep design in the sprint, run design QA before release and record every agreed trade-off.
Who owns what in the process
A film set has a person whose whole job is continuity: making sure the actor’s glass is half full in every take of the same scene, that the scar stays on the left cheek, that the clock on the wall does not jump from four to nine between shots. Nobody notices continuity when it works. Everybody notices the coffee cup that appears and disappears.
Product teams need the same thing, and it is usually missing, because every role owns a stage and nobody owns the thread between them.
- The founder or product lead owns the problem and the money: which business outcome matters, what it is worth and when to stop.
- The product designer owns the flow and the decisions encoded in it, from research findings to states on screen. They are the continuity person.
- Researchers, when you have them, own the quality of the evidence: who we talk to, what we ask and how sure we are.
- Engineers own feasibility and the build, and they should see the flow early enough to say “that data does not exist” before the design depends on it.
- QA owns the check that what shipped matches the flow, state by state.
- Analytics owns the plumbing of the measurement plan: events named after flow steps, and reports that answer the plan’s questions.
- Support owns the earliest warning signal after release, and deserves a seat at the diagnosis table.
The failure we meet most often is not a missing role. It is a missing handover between roles. Research findings that never reach the flow. A flow engineering sees for the first time in sprint planning. Analytics events named by whoever happened to implement them. Each gap is small. Together they explain why a product that was designed carefully ships differently from how it was designed.
In a small team one person wears several of these hats, and that is fine. What matters is that every stage you chose has a name next to it, and that someone owns the thread. A stage owned by “the team” is owned by nobody, and nobody is always very busy.
Decide how you will know it worked, before you release it
Shipping a change without deciding how success will be measured is running a race with no finish line. You run until you are tired, then call wherever you stopped a result. Everybody claps. Nobody knows whether you won.
The measurement plan belongs in the design process, not after it, because the flow already names the moments that matter. If the fix is meant to get more trial accounts to a first scheduled job, the plan says so before release: which event marks it, where it is measured, what the current level is, when the team will look again, and what it will do if nothing moves.

Write down the current level before anything changes. A baseline taken after release is not a baseline. It is a guess with a date on it. If the event you need does not exist yet, adding it comes before the release, not after the first meeting where someone asks whether the change worked.
A useful plan has a few properties:
- It measures behaviour tied to value, not activity. Page views and time on page are barking up the wrong tree. “First job scheduled” is what the business pays for.
- Each signal has a decision attached. If the number goes up, what do you keep? If it stays flat, what do you revisit? A metric with no decision attached is trivia.
- It watches for damage, not just success. Support tickets, errors, rollbacks and complaints tell you what the change broke, which the success metric will not.
- It has a date. “We’ll keep an eye on it” means nobody will.
Numbers tell you what happened. They rarely tell you why. So monitoring also includes a few follow-up conversations with the people the change was for, and a look at recordings of the new flow in real use. That closes the loop back to diagnosis. The next crime scene is usually already there, waiting for someone to notice.
The money logic is cold: without a baseline and a check date, you cannot tell whether the quarter you spent was an investment or a donation.
Audit check
For the last three product changes you shipped, find the success measure that was agreed before release and the date someone checked it.
Failure evidence
Success defined after launch, from whatever number went up. Dashboards nobody opens. No record of what the team decided when a number did not move.
Correction pattern
Write the measurement plan with the flow, attach a decision to every signal, set a review date and make the review a meeting, not a hope.
The mistakes that make the process expensive
Most over-budget design projects we inherit fail in a handful of predictable ways. None of them is exotic. Each is a drizzle on the day it happens and a flooded basement by the end of the year. The old saying goes “if it ain’t broke, don’t fix it”. Our version: if it is broke, find out where before you fix everything.
Naming the solution before the problem. “We need a redesign” is a verdict delivered before the investigation, like arresting the first person at the scene because they look guilty. Write the symptom and the evidence first. The solution will be cheaper for it.
Buying the package instead of the stages. The full process is sold because it is easy to quote, not because your product needs it. Every stage should name the decision it settles, or wait.
Mistaking documents for progress. A thick research report and a stack of personas feel like momentum. If they do not change a decision, they are expensive reading material.
Designing only the happy path. Real users arrive with empty accounts, half-imported data, missing permissions and slow connections. If the design covers only the perfect case, engineering will design the rest on the day, under deadline, without the flow.
Letting the design file drift. The flow says one thing, the design file another, production a third. From then on every conversation starts with “which version?”, and the answer is usually the one customers see.
Handing off by attachment. Sending a design file and a link to the prototype is a delivery, not a handoff. The questions start the moment engineering opens it, and someone has to be there to answer them.
Measuring whatever went up. Success defined after release, from the one number that moved, is not measurement. It is a press release.
Treating AI output as a decision. AI makes screens, summaries and prototypes cheap to produce. It does not decide which of them answers the right question. That part is still a person’s job, and still the part that makes money.
When a full redesign is the right call
We have spent a lot of words arguing against the default redesign, so let us be fair to it. Sometimes it is exactly what the evidence asks for.
Redesigning a product to fix one broken step is like moving house because one room is messy, and paying the removal van to carry the mess to a nicer address. But there are times when moving house really is the answer:
- the problems are everywhere, across roles and journeys, and they share a root cause in the product’s structure rather than in one step;
- the product has grown by accretion for years, every new feature bolted to the side, until nobody can say where anything belongs;
- the business has changed who it sells to, and the product still speaks to the old customer;
- the technology underneath is being replaced anyway, and rebuilding the interface on the old logic would waste the rebuild.
Even then, the redesign starts at the crime scene. Diagnosis tells you which problems the new structure must solve, which flows carry the most money, and which parts of the old product work well enough to keep. A redesign that skips that step is a clean new house with the same leaking pipes.
And a full redesign still ships in stages. Pick the journeys that carry the most value, redesign and release them one at a time, and measure each one. A big-bang launch concentrates all the risk into one day and makes it impossible to tell which change helped and which one hurt.
How long does the product design process take?
How long is a piece of string? The honest answer depends on which stages the problem needs, and nobody can tell you that before the diagnosis. Asking for a timeline before anyone has looked at the product is asking a vet how long the treatment will take while the dog is still in the car.
What we can tell you is what makes it longer or shorter:
- The number of stages the risk actually needs. One broken step with clear evidence is a different job from a product that has lost its way across ten journeys.
- Access to users and data. Research is quick when you can reach customers this week and the analytics can be trusted. It crawls when every interview needs three approvals and the events were never set up.
- Decision speed. The slowest stage in most projects is not design. It is waiting for someone to decide. A flow that needs sign-off from five stakeholders takes five calendars to approve.
- Roles and platforms. One role on one web app is simpler than managers, technicians and customers across web and two mobile platforms.
- Where the work stops. A diagnosis and a validated flow is a shorter engagement than one that runs through the build and the review after release.
Be wary of any quote that arrives with a fixed timeline before anyone has seen your product. It was not calculated. It was copied from the last proposal.
And weigh the cost of the process against the cost of the problem. If a broken step loses a steady stream of paid trial users every week, a slower, more “complete” process is not cautious. It is expensive. The fastest safe route to a validated fix is usually the best value, even when it looks less thorough on paper.
How ANODA runs the product design process
We start every engagement the same way: with what failed. Not with a mood board, not with a package, not with a promise. The first deliverable is a clear statement of the problem, the evidence behind it and the stages that will reduce the risk, in the order that makes sense for your product.
In practice, the diagnosis ends with a short document you can act on without us: the symptom in business terms, the evidence, the suspects we cleared and why, the stages we recommend and the ones we would park, where our part would stop, and how success will be measured. If the answer is “fix one step and measure it”, that is what it says.
From there, the route depends on what you need. We can take a product all the way, from discovery through research, flows, prototypes, interface and design system to implementation, release and monitoring. Or we can stop at the exact handoff your team wants: a diagnosis and a plan; a validated user flow and a tested prototype for your designers and engineers to carry on; production-ready designs with support during the build. There is no prize for buying more of us than you need, and we would rather be hired for the right half than blamed for the wrong whole.
ANODA brings the thread through the stages: the business problem becomes one flow, the flow becomes tested interaction and interface states, and the handoff keeps those decisions intact. In Vecna, our work connected the desktop operations console and a distinct Zebra handheld picker experience with a UI kit, screen map and prototype handoff. Different roles and working conditions needed different interfaces inside one coherent product model.
You get a focused route to a product that works better for the people using it, with the difficult decisions settled before they become expensive build surprises. Read more about how we work with product teams, stage by stage.
If you are still deciding what your product should become, rather than how to fix what it is, start one level up with our guide to product design strategy. Strategy decides where to go. The process in this article decides how to get there without paying for the scenic route.
The decision rule
Before you approve the next piece of design work, ask these questions in order. Stop at the first one without a clear answer. That is where the work starts.
- Can we state, in one business sentence, what is failing and what it costs?
- Do we have evidence that points to where it fails, and have we checked the other suspects?
- Do we know which stages reduce this risk, and which ones can wait?
- Is there one user flow for this journey that design, engineering, support and analytics all agree on?
- Have we tested the cheapest representation that could prove us wrong before paying for code?
- Is someone from design in the build, checking states and trade-offs?
- Did we decide, before release, how we will know it worked, and when we will check?
Diagnose first. Make the user flow the source of truth. Validate cheap representations before expensive implementation. Define how success will be observed after release. None of it is glamorous, and all of it is cheaper than the alternative, which is paying to acquire users and then paying again to find out why they left.
For more field notes on fixing products that lose money quietly, browse the rest of the ANODA UX blog.
Work with ANODA
Stop buying the whole process to fix one broken step.
We start with what failed, then take your product as far as you need: from discovery to release and monitoring, or to the exact handoff your team wants. You get a focused plan, a coherent experience and the design support that keeps the intended journey intact through the build.
Written by