In short
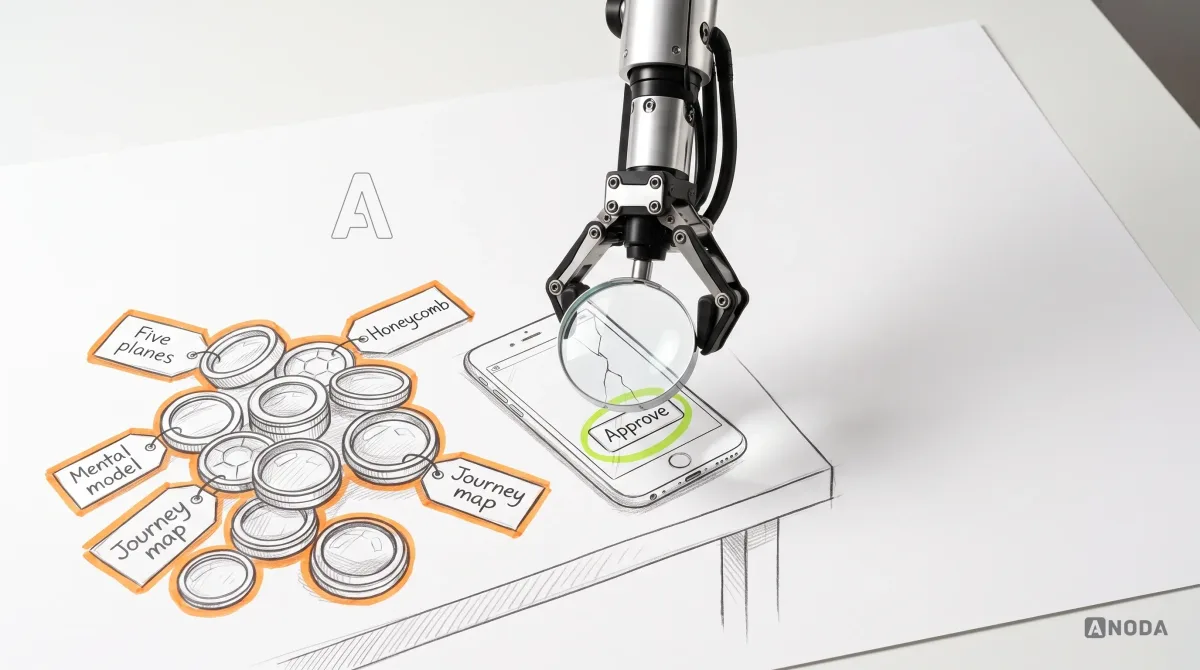
A user experience model is a lens, not an answer. Garrett's planes, the honeycomb, Norman's conceptual model, the gulfs, the three-factor model and journey maps each expose a different relationship, and none of them replaces evidence. Here is what each one explains, where it stops helping, how to pick the smallest one for the decision in front of you, and one stalled product seen through all of them.
In this article
- What a user experience model is, and what it is not
- Models, frameworks, processes, principles: sort the drawer first
- Mental models belong to users, not to your team
- Norman’s conceptual model: the one you actually control
- Garrett’s five planes: from strategy to surface
- The UX honeycomb: seven qualities, and you can’t max them all
- The gulfs of execution and evaluation: where interaction breaks
- The three-factor model: basics, performance and delight
- Journey maps: the model with a clock on it
- Maturity models grade the company, not the interface
- Which UX model answers which question
- One stalled product, seven models, six different problems
- How to apply a UX model without forcing evidence into a diagram
- Combining models without doing the work twice
- Where UX models lie to you
- Why ANODA carries the model into the interface
- Where your problem belongs
A user experience model is a simplified picture of one relationship in your product: between strategy and screens, between what users believe and how the system works, between what they expect and what they get. Pick one because it exposes the thing you are unsure about. Not because it looks clever on a slide. A model is a lens. It shows you one layer and hides the rest, and it never makes the decision for you.
We have seen more UX models on meeting-room walls than in actual decisions. Five planes, seven hexagons, three tiers of delight, a journey map the length of a corridor. Beautiful. Laminated. Ignored the moment someone asks, “So what do we build on Monday?”
That is framework theatre, and it is expensive. A team spends a month mapping, the diagram gets a round of applause, and the product ships exactly as it would have shipped anyway. Meanwhile the trial accounts you paid ads and sales calls to acquire keep stalling at the same step. Every week nobody fixes that step, you pay for those users twice: once to bring them in, and again to replace them.
Framework theatre is the pupil who spends three evenings colour-coding a revision timetable and never opens the textbook. The timetable is gorgeous. The exam still happens.
This guide sorts the models you will actually meet, says what each one explains and where it stops being useful, and then puts them all on the same stalled product so you can see how differently they read one problem.
What a user experience model is, and what it is not
A user experience model, or UX model, is a deliberately simplified description of how some part of an experience works. It picks a few variables, names the relationships between them and ignores everything else. That is the whole point. A model that included everything would be the product itself, and you already have one of those.
Doctors work the same way. An X-ray is brilliant for a broken wrist and useless for a sore throat. Nobody calls the X-ray wrong because it missed the tonsillitis. They call the doctor who ordered it for a sore throat wrong. UX models are the same kind of instrument. Garrett’s planes show dependencies between strategy and screens. The honeycomb shows competing qualities. A mental model shows what users believe. None of them shows everything, and all of them fail when you point them at the wrong question.
So the useful definition is practical. A UX model:
- Explains one relationship. Strategy to surface, belief to behaviour, expectation to satisfaction, step to step over time.
- Needs input. Research notes, analytics, support tickets, business goals, system constraints. No input, no model. Just a drawing.
- Produces a view you can act on. A gap, a mismatch, a priority, a broken step.
- Has an expiry date. It helps while the question is open. When the decision is made, it goes back in the drawer.
What a UX model is not: a process you follow, a checklist you complete, a deliverable you sell, or proof that your product is good. The map is not the territory. A team that forgets this ends up polishing the map while the territory quietly floods.
The money angle is simple. Choosing a model costs nothing. Running the wrong one for a quarter costs a quarter of salaries, plus every user who hit the broken step while the team was busy drawing.
Models, frameworks, processes, principles: sort the drawer first
Half the confusion around UX models comes from vocabulary. People say “model” for a process, “framework” for a diagram, and “principle” for anything they read on a poster. Then they wonder why the team argues past each other for an hour.
Here is how we sort the drawer before any project starts:
| Term | What it describes | Whose head it lives in | Typical example | What it helps you do |
|---|---|---|---|---|
| User experience model | One relationship inside the experience | Shared by the team, built from evidence | Garrett’s five planes, the UX honeycomb, the three-factor model | See where a problem sits and what it depends on |
| Mental model | What a user believes about how the product works | The user’s | “A report is a folder I send to my manager” | Predict what people will try, and where they will get it wrong |
| Conceptual model | How the product is meant to work, as the design team intends it | The design team’s, expressed through the interface | “A report is a batch of expenses approved as one unit” | Make the product explainable, and check it against users’ beliefs |
| Journey map | One person’s steps, thoughts and feelings over time | Built by the team from research | Manager’s week of approving expenses | Find the moment where the experience breaks |
| UX framework | A structure for making a type of decision | The team’s working method | Double Diamond, Lean UX, HEART | Organise the work around a decision |
| UX process | The sequence of work from problem to release | The team’s | Research, flows, prototypes, testing, delivery | Get from a problem to a shipped answer in order |
| Principle or heuristic | A rule of thumb for good interface behaviour | The profession’s shared knowledge | Nielsen’s usability heuristics | Spot likely problems quickly |
| Maturity model | How well an organisation practises UX | The organisation’s | The NN/g UX maturity model | Plan how a company builds UX capability |

Two lines matter most in that table. A framework organises the work. A model explains the experience. We cover the working structures — Double Diamond, Lean UX, HEART and the rest — in our guide to choosing UX design frameworks. This article stays with the models: the lenses you look through, not the plans you follow.
Nielsen’s heuristics are a good example of a principle doing a principle’s job. Jakob Nielsen published the final set of ten in 1994, and Nielsen Norman Group, his firm, still calls them, as of 2026, “broad rules of thumb” rather than specific guidelines. They tell you what probably hurts. They do not tell you why your particular users are stuck, or what to build instead.
Mental models belong to users, not to your team
A mental model is what a user believes about how your product works. Nielsen Norman Group defines it in almost exactly those words, and the short definition is the right one: belief, not truth.
Think of a guest in your flat trying to turn on the hallway light. They have never seen your wiring diagram. They flip the switch nearest the door, then the one next to it, then the one that turns out to control the extractor fan in the bathroom. Their model of your flat is built from every other flat they have lived in. Your wiring is not wrong. It is just not what they expected, and they are the one standing in the dark.
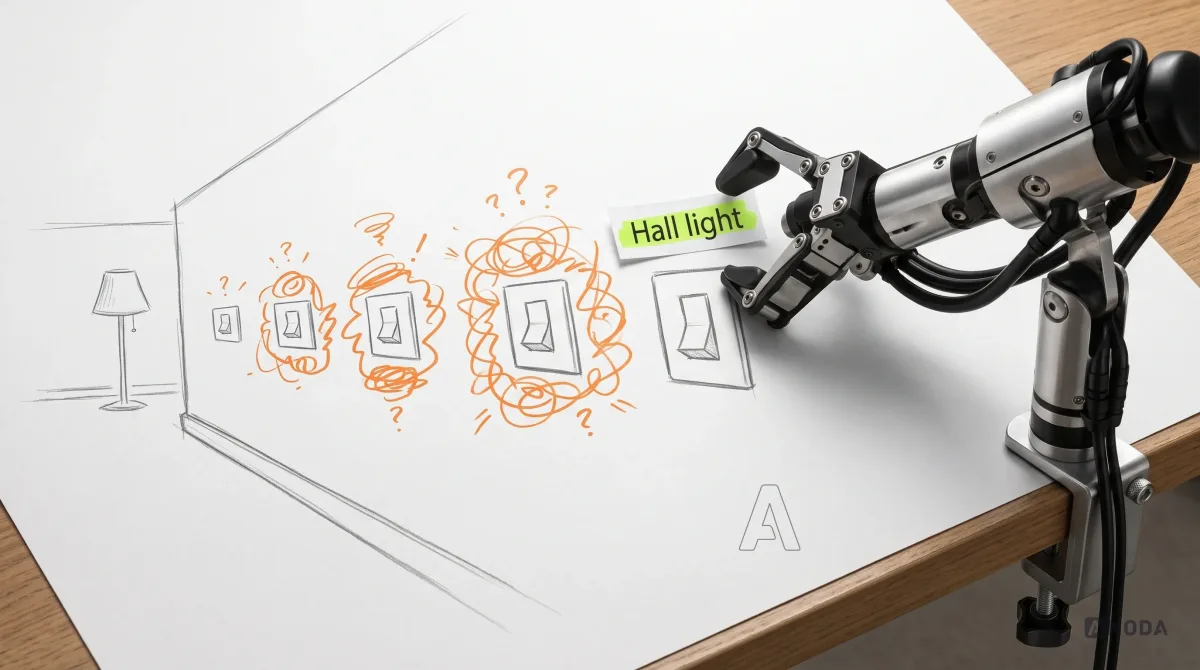
That is how users meet your product. They arrive with models from email, from spreadsheets, from the tool they used at their last job, from your competitor. They act on those models, and when your product behaves differently, they do not update their beliefs politely. They decide the product is broken, confusing or “not for us”.
Three rules keep this concept honest:
- Mental models are discovered, not designed. You find them in interviews, observation, support tickets and the workarounds people build. You cannot write them in a workshop. A “user mental model” drawn by the team at a whiteboard is the team’s guess about the user’s head, which is two steps removed from evidence.
- Different users hold different models. An employee filing expenses and a manager approving them can hold completely different beliefs about the same report. Averaging them gives you a model nobody actually holds.
- You do not fix a mental model by explaining harder. Onboarding tours, tooltips and help articles try to argue users out of what they believe. It rarely works. Usually you either design to match the model, or you make the difference visible at the exact moment it matters.
Getting this wrong is expensive in a very specific way. The product works, the demo is flawless, and paid-for users still fail at the same step, because the step contradicts what they believe. The team calls it “user error”. The churn report calls it revenue.
Use it when you see repeated “wrong” behaviour that is actually consistent: people keep clicking the same wrong thing, asking the same question in support, or building the same workaround. Inputs: interviews, observation, tickets, session recordings. Output: a short description of what each user group believes, and where that belief collides with the product. Stage: any, but most valuable before a redesign and after a failed launch. Limit: it describes beliefs, not what to build. That is the next model’s job.
Norman’s conceptual model: the one you actually control
If the mental model is the user’s belief, the conceptual model is yours: how the product is meant to work, as the design team understands it. Don Norman, who wrote The Design of Everyday Things, framed the relationship with three parts, and it is still the cleanest way to see the problem.
- The designer’s model. How the team thinks the product works.
- The system image. Everything the product itself communicates: the screens, the labels, the states, the messages, the documentation.
- The user’s model. What the user ends up believing, built from the system image and from everything they bring with them.
Norman’s point, repeated on his own site, is that the designer never gets to talk to the user directly. The product carries the whole conversation. On jnd.org he puts it this way: the designer “only talks to the user via the product itself”.

It is a voicemail you cannot take back. You record the message once, you cannot see the listener’s face, and you cannot clarify when they frown. Whatever the recording says is all they get. If your conceptual model lives in a product spec, a Notion page and the head of your lead designer, and the interface does not show it, the user will build their own. It will be different. It will be confidently wrong.
In practice a conceptual model is small and concrete. It names the objects in the product (a report, an expense, an approval, a payment), the actions each object allows, the relationships between them and the states they move through. A good one fits on a page. If your team cannot write it down in plain language, the interface cannot possibly express it, and every screen will quietly invent its own version.
The comparison between conceptual and mental model is where the money is found. Where they match, users succeed without help. Where they collide, you get the support tickets, the abandoned trials and the “it’s too complicated” feedback that nobody can turn into a task. Norman’s remedy, in the 2013 revised edition of his book and throughout his writing, is to build a clear, coherent conceptual model and make the product express it, so users can form an accurate model of their own.
Use it when the product has grown by accretion, and nobody can explain in two sentences what the main objects are and how they relate. Inputs: the current product, the data model, the team’s own vocabulary, and the user mental models you have evidence for. Output: a one-page object-and-action model, plus a list of collisions with users’ beliefs. Stage: early concept work, before a redesign, or when adding a major feature. Limit: it describes intent. Whether the interface actually communicates it is a question for testing, not for the diagram.
Audit check
Ask three people on the team to write, separately, what the product’s main objects are and what users can do with each. Then ask five users to explain the same thing in their own words.
Failure evidence
The three team answers disagree with each other. Users describe objects the product does not have, or miss ones it depends on.
Correction pattern
Agree one conceptual model in plain language, check every screen’s labels and states against it, and redesign the collisions users actually hit first.
Garrett’s five planes: from strategy to surface
Jesse James Garrett’s elements of user experience is probably the most reproduced UX model in the world. It started as a one-page diagram, dated 30 March 2000 on Garrett’s own site, and grew into his book The Elements of User Experience. It splits the experience into five planes, from the most abstract to the most concrete:
- Strategy. What the business wants from the product and what users want from it.
- Scope. Which features and content are in, and which are out.
- Structure. How the pieces fit together: information architecture and interaction design.
- Skeleton. The arrangement of elements on the screen: interface, navigation and information design.
- Surface. What people actually see: the visual design.

The model’s real value is the dependency. In chapter two of the book, which Garrett publishes on his site, each plane depends on the one below it: surface on skeleton, skeleton on structure, structure on scope, scope on strategy. A choice on a lower plane limits what is possible on the planes above it.
Picking the surface while strategy is unsettled is choosing tablecloths before deciding whether you are opening a steakhouse or a sushi bar. Lovely tablecloths. Wrong restaurant. We see this in redesign after redesign: a new visual language, new components, a new icon set, sitting on top of a scope nobody questioned and a structure nobody tested. The product looks new. The activation curve looks exactly the same, and the redesign budget is gone.
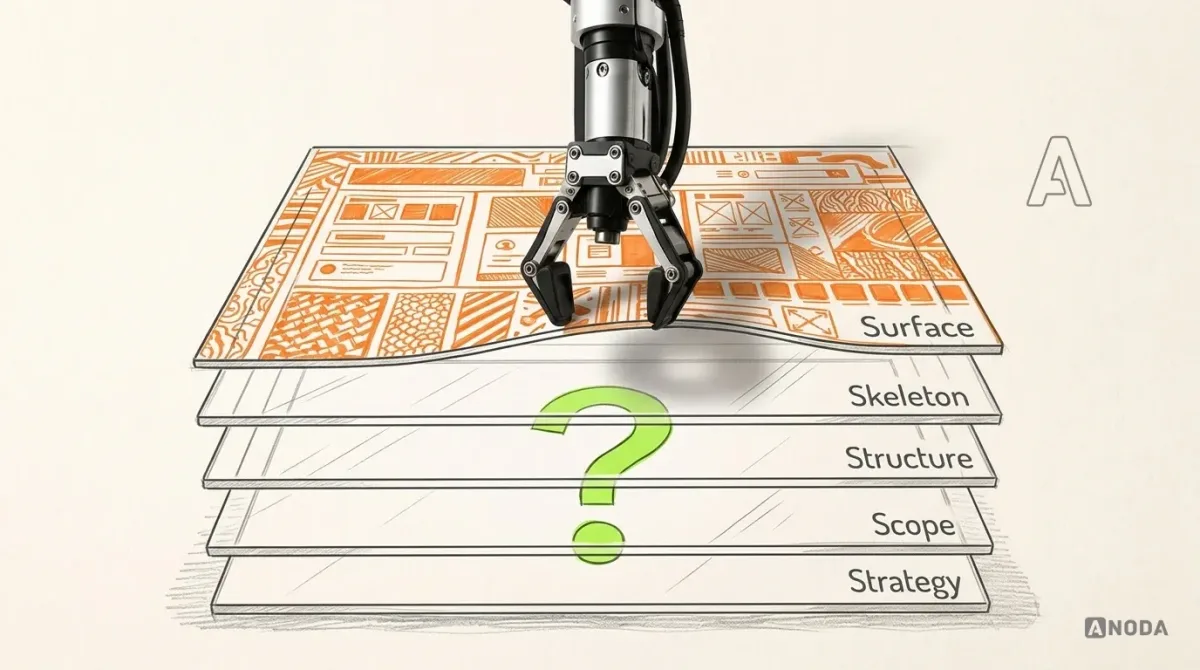
The most common misreading is to treat the planes as a waterfall: finish strategy, then start scope, and so on. Garrett says the opposite. His recommendation is that work on a plane cannot finish before work on the planes below it has finished. You can start sketching screens early. You just cannot lock them before the scope is settled. A builder can order the windows before the walls are up. He cannot fit them.
For diagnosis, the planes are a triage tool. When a product has a problem, ask on which plane it actually lives. “Managers approve expenses in email instead of the app” can be a strategy problem (in-app approval was a goal for the vendor, never for managers), a scope problem (partial approval does not exist), a structure problem (pending approvals are buried three levels deep), a skeleton problem (the button is below the fold) or a surface problem (approved and pending look identical). Each answer leads to a different fix and a very different bill. Fixing a strategy problem on the surface plane is the most common way we see teams burn a quarter.
Use it when a team is arguing about screens and you suspect the real disagreement is about scope or strategy. Inputs: business goals, user needs from research, the feature list, the current navigation and screens. Output: a map of which decisions are settled on which plane, and which plane a given problem lives on. Stage: new products, redesigns, and diagnosis of a problem nobody can place. Limit: it was written for the web of 2000. It says little about time, emotion, multi-device journeys or AI behaviour, and it does not tell you what users believe. It organises the questions. It does not answer them.
The UX honeycomb: seven qualities, and you can’t max them all
Peter Morville published the user experience honeycomb on his site, Semantic Studios, on 21 June 2004. It names seven facets of the experience: useful, usable, desirable, findable, accessible, credible and valuable. It was designed to push conversations beyond usability, and it did.
The honeycomb is a quality model. It does not describe structure or time. It asks: which qualities matter for this product, and which ones is it failing? That makes it useful for a quick diagnostic and for settling arguments about priorities.

Here is the part people skip. Morville himself wrote that the honeycomb helps teams “define priorities”, and that choosing between facets depends on your balance of context, content and users. It is not a checklist to max out. A product that tries to be equally desirable, credible, findable and everything else ends up a jack of all trades and master of none.
Think of a decathlon. The decathlete is impressive, but a sprinter who scores zero at shot put still wins the 100 metres. An expense tool for finance teams needs to be credible and useful before it is desirable. A consumer habit app is often the other way round. The honeycomb is valuable precisely because it forces that choice into the open, where the team can argue about it with evidence rather than taste.
In practice we use it in three moves. Rate each facet for one user group, with evidence next to every rating. Pick the two facets that are failing and matter most for the business. Ignore the rest until those two move. The evidence column is not optional. A honeycomb rated in a meeting from memory is seven opinions arranged in a pretty shape.
Use it when the team has a vague sense that “the UX is bad” and needs to say which quality is actually failing. Inputs: research findings, usability test results, reviews and support themes, analytics per user group. Output: a ranked list of failing qualities for a specific user group. Stage: live products, audits, competitive comparisons. Limit: it does not tell you where in the flow the problem sits, or why. “Not findable” is a symptom. The cause lives on one of Garrett’s planes, or in a mismatch of models.
The gulfs of execution and evaluation: where interaction breaks
This is the model we reach for most often when a specific interaction fails. The gulf of execution is the distance between what users want to do and working out how to do it in your product. The gulf of evaluation is the distance between what the system did and users understanding what happened. Nielsen Norman Group traces the terms to Ed Hutchins, Jim Hollan and Don Norman in 1986, and Norman later developed them in The Design of Everyday Things.
A hotel shower explains both. Two identical unmarked knobs: which one is hot, and which way is more? That is the gulf of execution. You turn one, the water runs, and you have no idea whether it is warming up or whether you have just made it colder. That is the gulf of evaluation. Every guest stands there with a hand under the water, half a minute of their holiday gone, getting it wrong in slightly different ways.

The gulfs are practical because they turn vague complaints into two concrete questions for every step:
- Execution. Can users see what they can do here, in their own terms? Is the action they want available, labelled the way they think about it, and reachable without a hunt?
- Evaluation. After acting, can users tell what happened, what state things are in now, and what happens next?
Most “confusing” screens fail one of the two, and the fixes are different. A failure of execution needs better signifiers, labels, structure or options. A failure of evaluation needs visible states, feedback and consequences. Teams that treat both as “make it simpler” usually remove the one piece of information users needed.
Money leaks through both gulfs in different ways. Execution failures show up as drop-off: users who never find the action and leave. Evaluation failures show up as support volume and duplicate actions: users who did the thing, could not tell, and did it again or phoned you. Both are users you paid to acquire, doing extra work to use the thing they already bought.
Use it when a specific step fails and people describe it as “confusing”. Inputs: usability test recordings, session replays, support tickets about that step, the screens and their states. Output: a list of execution gaps and evaluation gaps per step, each with a design change. Stage: prototype testing, live product diagnosis, audit of a critical flow. Limit: it works step by step. It will not tell you whether the flow itself is the right one, or whether the step should exist at all.
The three-factor model: basics, performance and delight
The idea behind it is simple: product qualities do not all affect satisfaction the same way. Some qualities cause anger when missing and go unnoticed when present. Some make things better the more you have. Some delight when present and cost nothing when absent. The three-factor model of user experience is one formal version of that idea for software.
One published version under that name is a 2022 IEEE conference paper by Emmanuel Mkpojiogu and colleagues. Its abstract, on IEEE Xplore as of 2026, arranges UX qualities into a hierarchy of three factors:
- Expected ergonomic qualities that only work in one direction: their absence hurts, their presence is taken for granted. Correct totals. A receipt you can read. Approving from a notification.
- Expected hedonic qualities that work in both directions: better is better, worse is worse. How fast reimbursement arrives. How few steps an approval takes.
- Unexpected hedonic qualities that only work upwards: nobody misses them, but they please when they appear. Card transactions matched to receipts automatically.
Use the three categories to expose the roadmap decision: which missing basics block the core task, which improvements make it faster and which additions create delight.

The practical value is in the sorting. Picture a school that builds a planetarium on the roof while the toilets have been out of order since September. Parents do not write thank-you letters about the planetarium. They write angry emails about the toilets. Delight does not compensate for missing basics, and product teams love to build delight, because delight demos well and basics do not.
We see the same pattern in almost every roadmap we audit: an AI summary, a playful empty state and a dark mode, shipped while the export still breaks on large files. The delight features got a launch post. The broken basics got the churn.
Use it when the roadmap is full of new features and satisfaction is flat or falling. Inputs: complaints, support themes, reviews, feature usage, research on what users expect as standard. Output: a sort of qualities into basics, performance and delight, and a check on which tier the roadmap is actually funding. Stage: live products and roadmap planning. Limit: qualities move between tiers over time, today’s delighter becomes tomorrow’s basic, so revisit the categories as user expectations change.
Journey maps: the model with a clock on it
Most UX models are frozen in time. A journey map is the one that has a clock on it. Nielsen Norman Group defines it as a visualisation of the process a person goes through to accomplish a goal, and lists the usual parts: an actor, a scenario with expectations, phases, the actions, mindsets and emotions in each phase, and the opportunities that follow.
That time dimension is exactly what the other models miss. You can have the comfiest seat on the train and still miss your connection, because nobody put the platform number on the board. Each screen can pass every heuristic, and the experience can still fail in the gap between two of them, often outside your product: in an inbox, in a spreadsheet, in a phone call to finance.

Journey maps fail in two predictable ways. First, they are drawn from the team’s assumptions and then presented as research. A map built in a workshop, with emotions guessed by people who have never watched a user, is fan fiction with swim lanes. Second, they are drawn once, framed and never updated. The product changes, the map stays, and six months later it is describing a product that no longer exists.
A useful journey map is narrow. One actor, one scenario, one goal, built from observation and interviews, with every emotional dip tied to something a real person did or said. Then it earns its keep by pointing at the one or two moments where the experience breaks and money leaks: the step where trials stall, where people switch to a workaround, or where they call support.
Use it when the problem spans several steps, channels or people, and no single screen looks broken. Inputs: interviews, observation, analytics across the steps, support contacts, the touchpoints outside your product. Output: a map of one journey with its breaking points ranked. Stage: discovery, before a redesign of a multi-step flow, and after launch to find where adoption stalls. Limit: it shows where and when, not why. The why usually needs a mental model or the gulfs. For the step-by-step mechanics inside the product, a user flow is the sharper tool.
Maturity models grade the company, not the interface
UX maturity models appear in this conversation all the time, and they belong to a different job. They assess how well an organisation practises UX, not how good a product’s experience is.
Nielsen Norman Group’s model is a typical example. As published on its site as of 2026, its six stages run from Absent through Limited, Emergent, Structured and Integrated to User-Driven, and NN/g says explicitly that maturity should be evaluated for a whole organisation, looking at its processes, resources, tools, operations and leadership support.
A hospital accreditation certificate tells you that the hospital has processes. It does not tell you whether your operation went well. A company can be at a respectable maturity stage and still ship a checkout that is a complete mess. A scrappy three-person team with no stages at all can ship an onboarding that works beautifully, because two of the three people watched users every week.
Use a maturity model when the question is organisational: why does research never reach the roadmap, who owns the design system, how do we build a UX practice. Do not use it to judge whether your product is easy to use, and do not let a good maturity score end a conversation about a bad flow. The users paying for the product have never seen your maturity assessment, and they do not care.
Which UX model answers which question
Now the useful part: matching the model to the decision. Start with the question you are stuck on, not with the model you like.
| Model | The question it helps answer | Inputs it needs | What it produces | Best product stage | Strength | Where it stops helping | Concrete example |
|---|---|---|---|---|---|---|---|
| User mental model | What do users believe this does? | Interviews, observation, tickets, workarounds | Beliefs per user group and where they collide with the product | Before a redesign, after a failed launch | Explains “user error” that keeps repeating | Says nothing about what to build | Managers think each receipt is a separate request |
| Conceptual model (Norman) | How is this product meant to work, and does the interface say so? | Product, data model, team vocabulary, known mental models | One-page objects, actions, relationships, states | Concept, redesign, major new feature | Makes the product explainable and consistent | Describes intent, not what users perceive | “A report is a batch approved as one unit” |
| Five planes (Garrett) | On which layer does this problem live, and what does it depend on? | Business goals, research, feature list, structure, screens | Settled and open decisions per plane | New product, redesign, unplaced problems | Stops surface fixes for strategy problems | Weak on time, emotion and multi-channel journeys | Approval buried three levels deep: structure plane |
| UX honeycomb (Morville) | Which quality is failing, and which ones matter most? | Research, test results, reviews, analytics | Ranked failing qualities per user group | Live product, audit, competitor review | Forces an explicit priority | Does not locate the problem in the flow | Findable and credible fail for managers |
| Gulfs of execution and evaluation | Can users act here, and can they tell what happened? | Test recordings, replays, tickets, screen states | Execution and evaluation gaps per step | Prototype testing, critical-flow audit | Turns “confusing” into specific fixes | Step-level only; does not question the flow | “Processing” says nothing about payment |
| Three-factor model | Are we funding delight while basics are missing? | Complaints, reviews, expectations research, usage | Qualities sorted into basics, performance, delight | Live product, roadmap planning | Exposes a roadmap chasing demos | Tiers shift as expectations change | Auto-matching built before approval from a notification |
| Journey map | Where, across time and channels, does it break? | Interviews, observation, cross-step analytics, support | One journey with ranked breaking points | Discovery, multi-step redesign, post-launch | Sees the gaps between screens and channels | Shows where, not why | The stall is between the digest email and the app |
| Maturity model | How well does the organisation practise UX? | Processes, roles, tools, leadership support | Stage and capability plan | Organisational planning | Plans capability building | Says nothing about interface quality | Research never reaches the roadmap |

Two rules make the table usable. First, choose the smallest model that exposes the uncertainty. You do not hire a structural engineer to hang a picture. If the problem is one step that confuses people, the gulfs will do; a full journey map and a honeycomb workshop will just delay the fix. Second, if no model on the list fits your question, that is not a reason to invent one. It usually means the question is not a UX-model question at all. It may be pricing, positioning or a bug.
One stalled product, seven models, six different problems
Theory is cheap. Here is how differently the models read the same problem. The product is a fictional B2B expense tool; the numbers are illustrative, the pattern is one we meet again and again in B2B products.
The symptom: companies sign up for a trial, employees submit expense reports, and then the reports sit. Managers do not approve them in the app. Finance chases managers by email, employees ask finance whether they have been paid, and a large share of trial companies never reach their first reimbursement through the product. That first reimbursement is the moment the tool proves its worth. Every trial that stalls before it is an acquisition cost with no customer at the end.
The team’s first instinct was the usual one: “Let’s redesign the approvals screen.” Here is what each model says instead.

Mental model against conceptual model. Interviews with managers show that they think of each receipt as its own request, the way they treat email: approve this one, question that one, move on. The team then writes down its own model and discovers that a report is a batch approved as one unit, and that nobody ever decided this. It came from the first version of the database. So when a manager wants to approve six items and query one, the product offers “Approve all” or “Reject all”, and the manager replies by email instead. The designer’s model, the system image and the user’s model disagree about the most important object in the product.
Garrett’s planes. The problem is not on the surface. Partial approval is missing from the scope, and pending approvals live under Reports, then Team, then Pending, in the structure. A visual redesign of the approvals screen would have polished a screen that managers rarely reach and that cannot do what they need.
The honeycomb. For managers, the product is failing on findable (pending items are buried) and credible (finance does not trust the scanned totals, so managers double-check against paper). Desirable is irrelevant here. Nobody wants a beautiful expense tool. They want it to be over quickly.
The gulfs. Execution: the manager cannot approve part of a report, so the action they want does not exist. Evaluation: after approving, the status says “Processing”, which tells nobody whether the employee will be paid or when. That second gap explains a whole category of “has this gone through?” emails to finance.
The three-factor model. Partial approval and approving from a notification are expected basics for managers. Their absence causes complaints, and their presence would be taken for granted. The roadmap, meanwhile, had automatic card matching at the top: a genuine delighter, built for a customer who cannot yet complete the basic job.
The journey map. Across the week, the break is not in the app at all. It sits between the Monday digest email and the app: the email lists the reports, has no actions, and teaches managers that email is where approvals happen.
Seven models, six readings, and they do not all point at the same fix. That is not a weakness. It is the whole value. The screen redesign the team started with would have addressed, at best, a fraction of one reading. The models together say: this is a mismatch between a batch-based conceptual model and a receipt-based mental model, made worse by a digest email that teaches the wrong habit and a status that says nothing.
The decision that follows is also narrower and cheaper than a redesign: change the approval unit to the individual expense, add approve and query actions to the digest email and the notification, and replace “Processing” with a status that names the payment date. Then test it with a handful of managers before building anything else. The card matching waits.

Notice what the models did not do. They did not produce the evidence. The interviews did. Every reading above depends on something someone observed or heard. Without that, the same seven models would have produced six confident guesses, beautifully drawn.
How to apply a UX model without forcing evidence into a diagram
The failure we see most often is not choosing the wrong model. It is using the right one backwards: picking a diagram first, then stuffing whatever the team believes into its boxes until every box is full. A square peg in a round hole, and a diagram that looks complete precisely because nobody checked it.
Here is the order we work in. It is a real sequence, because each step needs the output of the one before it.
- Name the product decision. One sentence, with an owner and a deadline. “Should approvals move to individual expenses before we build card matching?” is a decision. “Improve the UX of approvals” is a wish.
- Collect user, business and system evidence. What users do and say, what the business needs from this flow and what it costs, and what the system can and cannot do. All three, because a model built on user evidence alone will cheerfully propose something the database cannot support.
- Choose the smallest model that exposes the uncertainty. If the doubt is about beliefs, a mental model. If it is about one step, the gulfs. If it is about which layer is broken, the planes. One model, maybe two.
- Map the evidence into the model. Put only what you have evidence for into the boxes, and tag each entry with its source.
- Mark assumptions and gaps. Every empty box and every entry without a source is an assumption. Write them down as a list, ranked by how much damage they do if they are wrong.
- Make the decision. The model should now show you which option the evidence supports and which assumptions you are betting on. Decide, and write down what would change your mind.
- Validate through research or product behaviour. Test the riskiest assumptions with users, or ship a narrow change and watch what people actually do.
- Revise the model when the evidence changes. Update it, or throw it away if the question it answered is closed.

Step eight is the one teams skip, and it deserves a thought experiment. Bayes’ theorem is, at heart, a rule for updating what you believe when new evidence arrives. A UX model should behave the same way. It is your current best belief about how the experience works, held with a confidence that matches the evidence. When new evidence arrives, the model changes. A model that never changes after launch is not stable. It is abandoned.

The money logic is blunt. Every assumption you leave unmarked is a bet placed with the engineering budget. Some bets win. The ones that lose cost a quarter of build time, and nobody notices until the release is out and the numbers do not move.
Audit check
Take the last UX model or map your team produced. Tag every box with its source: research, analytics, support data, a stakeholder’s opinion, or nothing.
Failure evidence
Most boxes trace back to a workshop or to nothing. Nobody can name the decision the model was built for.
Correction pattern
Write the decision on top, strike or mark every unsourced box as an assumption, rank the assumptions by risk, and research the top two before anyone draws another box.
UX research
Your model is mostly assumptions? Good. Now you know what to find out.
We run the interviews, observation and data work that turn the riskiest boxes into evidence, so your next decision rests on users, not on the loudest voice in the workshop.
Combining models without doing the work twice
Models combine well when each one answers a different question and hands its output to the next. They combine badly when three models are run in parallel on the same question, each with its own workshop, and produce three slightly different answers that someone then has to reconcile.
That is two sheepdogs herding the same flock in opposite directions. The sheep go nowhere, both dogs are exhausted, and the farmer is paying for two dogs.
The combinations that work share one research round and feed each other in order:
- Mental model into conceptual model. Research reveals what users believe. The team then designs a conceptual model that matches it, or deliberately makes the difference visible.
- Journey map into the gulfs. The journey map finds the step where the experience breaks. The gulfs then diagnose that step in detail.
- Planes into the honeycomb. The planes locate a problem’s layer. The honeycomb decides which quality to prioritise when fixing it.
- Three-factor model into the roadmap. Once the other models have found the failing basics, the three-factor sort protects them from being pushed down the roadmap by shinier delighters.

Two rules keep the combination lean. One research round per decision, reused by every model that needs it, instead of each model commissioning its own. And a named owner for each model, whose job includes retiring it. Stabilisers on a child’s bike are essential in the first week and a liability in a race. A model that helped you through discovery can hold you back once you are optimising a live product.
If a combination starts producing documents faster than decisions, stop. The documents are not the product, and nobody will ever pay you for them.
Where UX models lie to you
Every model on this list is useful. Every one of them can also mislead a team that forgets what it is. These are the cautions we give every client before a model goes on the wall.
Models simplify reality, on purpose. That is their job. It also means that everything the model leaves out is still happening. The honeycomb has no box for the finance team’s month-end panic. The planes have no box for the email digest. When something important does not fit the model, the model is wrong for this question, not the reality.
A polished diagram is not user evidence. A weather forecast painted in beautiful watercolours is still a guess about tomorrow. Diagrams get more convincing as they get more polished, and nothing about polish makes them more true. Polished crap is still crap. It just photographs better. The most dangerous artefact in a product team is a beautifully designed journey map that nobody checked with a single user.
Broad quality models do not replace workflow research. The honeycomb or the three-factor model can tell you that something is failing. They cannot tell you how a manager actually approves expenses on a Monday morning with forty items and a meeting in ten minutes. Only watching that manager can. In complex B2B products, where workflows are long and roles differ, this gap is where most of the value lies, and where most redesigns go wrong.
Mental models belong to users, not to the design team. It bears repeating because it is the most common screw-up we see. A team writes “the user’s mental model” on a slide, fills it with its own assumptions and then designs against it. That is the team’s model wearing the user’s name badge. The emperor’s new clothes, with a persona photo.
Maturity models assess organisations, not interfaces. A good maturity stage is not evidence that any particular flow works, and a poor one does not mean it fails. Keep the two conversations apart.
Models expire. The question changes, the product changes, the users change. A model kept on the wall after its question is closed becomes decoration, and decoration has a nasty habit of turning into doctrine.
Why ANODA carries the model into the interface
Another polished diagram cannot fix a mismatch between what users expect and what the product lets them do. ANODA carries the decision into the objects, labels, actions and states people actually meet.
Our MantisHub work connected issue workflows, filtering, notes and related actions in one coherent interface and UI kit for the client development team. We bring that same continuity to your product: the model stops being a meeting-room artefact and becomes a journey customers can understand, with a handoff engineering can build.
Where your problem belongs
Models are cheap. Knowing which one to use, feeding it real evidence and turning its output into a design decision is the actual work. Here is where that work sits, depending on where you are.
You have a live product and the symptoms are scattered. Support tickets, stalled trials, complaints nobody can pin to one screen. Before any model can guide a redesign, you need a structured view of where the experience breaks and what it costs. That is what a UX audit is for: it turns scattered symptoms into a prioritised diagnosis.
You have the model, and it is mostly assumptions. You know which question matters, but not what users believe, how they work or where they stall. Then the next step is UX research aimed at the riskiest assumptions, not another workshop.
You know the problem and need the answer designed. The evidence is in, the model points at the mismatch, and now it has to become flows, states and screens your engineers can build. That is UI/UX design work: turning the chosen model into an interface that tells users how the product works, without a tour.
In each case we choose the minimum set of models that exposes the decision, use them inside the research, audit or design work, and drop them when they stop helping. We do not sell diagrams as outcomes. Nobody ever raised a round, renewed a contract or activated a trial with a honeycomb.
UI/UX design
Stop drawing the model. Start shipping the decision.
Bring us the product, the evidence you have and the step where users stall. We pick the lens that exposes the real problem and design the flows and screens that fix it.
Written by